I presented Tracing an LLM API Request as part of Major League Hacking’s Hacktoberfest 2026 livestream series.
In this visual talk, we follow a single LLM API request from the client to the GPU and back, exploring the inference pipeline, performance bottlenecks, and optimizations that make modern LLM serving possible.
Visual Explainer (5 min)
A short, animated journey through the LLM inference pipeline, from API gateway to GPU execution and streamed response.
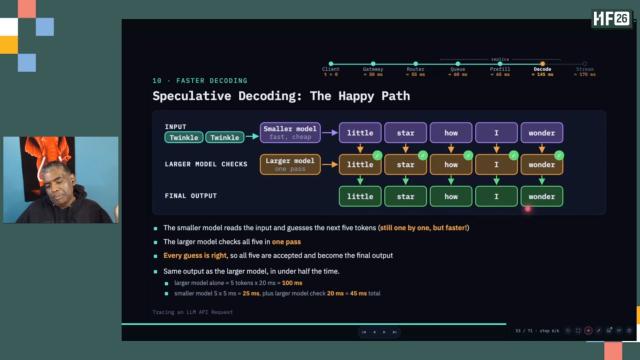
Along the way, see how techniques like KV caching, cache-aware routing, continuous batching, and speculative decoding improve performance.
Watch the Full Talk (45 min)
Watch the full Hacktoberfest livestream for a deeper walkthrough of the inference pipeline, practical examples, and Q&A.
Resources
- 🎥 Full session recording
- Hacktoberfest 2026 | Event schedule | MLH on Twitch
- Talk announcement
- Community feedback 👍: 1
Gallery